This guide examines Uni Tms as a core platform for enterprise logistics visibility, workflow control, and performance management. In the background, it reviews how transportation and warehouse systems align, what data quality demands exist, and why integration matters. The article then offers objective selection criteria, operating conditions, and practical FAQs for stakeholders evaluating deployments.
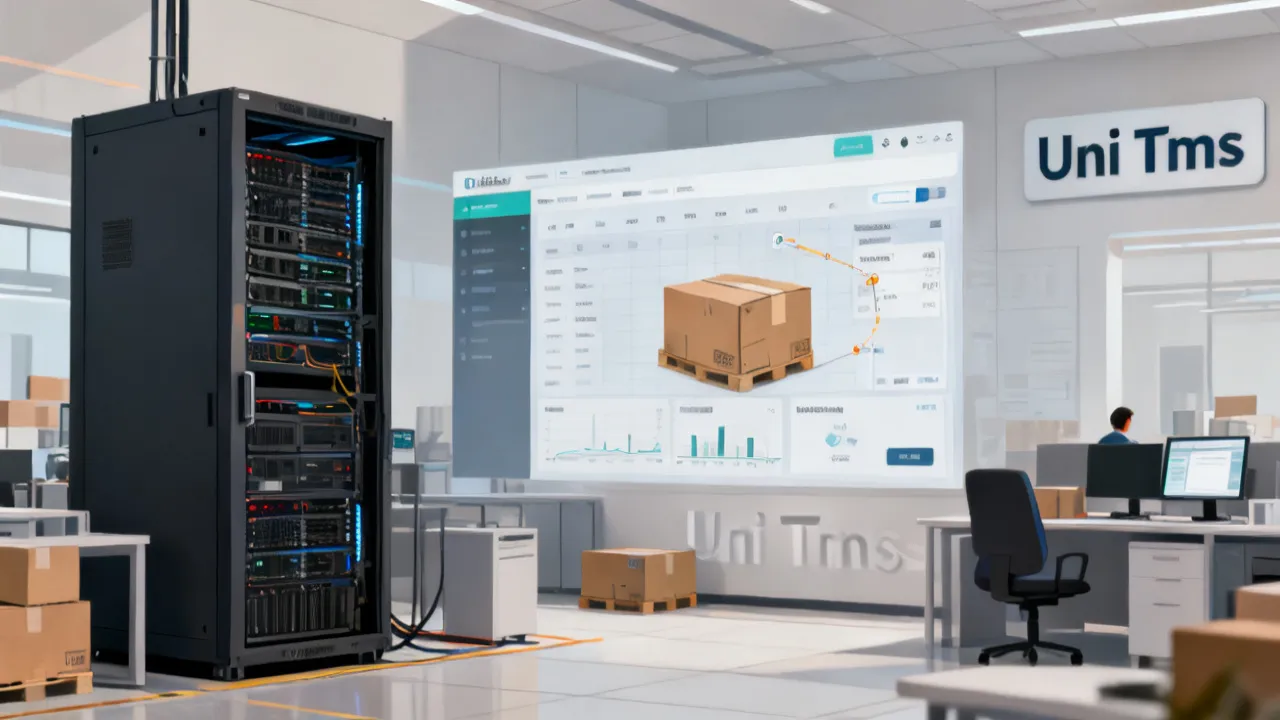
Uni Tms is often evaluated by operations, IT, and supply-chain leaders as a practical foundation for managing end-to-end logistics workflows—especially where shipment status visibility, rule-based execution, and coordination across warehouse and transport activities are priorities. Unlike standalone tools that address one segment, a well-scoped Uni Tms deployment typically aims to unify data flows and standardize how teams act on that data. In practical terms, decision-makers look for system clarity: consistent documentation, traceable events, and repeatable processes that reduce operational ambiguity.
From an expert perspective, the very important question is not merely whether Uni Tms can “track shipments,” but whether the platform can support the operational reality of your organization: the number of facilities involved, the variability of carriers or routing rules, the maturity of your master data, and the degree of integration needed between procurement, inventory, customer order management, and transportation execution. When those factors are aligned, Uni Tms can function as the operational layer that turns logistics information into reliable action.
In many enterprises, the hidden cost of logistics complexity shows up as “time spent reconciling.” Dispatch teams spend time confirming whether tracking numbers are correct, customer service teams spend time answering status calls because updates arrive late or inconsistently, warehouse supervisors spend time interpreting incomplete milestones, and planners spend time correcting scheduling decisions because upstream commitments weren’t properly captured. A carefully implemented Uni Tms reduces reconciliation work by aligning event definitions, assigning clear operational responsibility, and providing rule-driven transitions that make the logistics process less dependent on individual heroics.
Just as importantly, Uni Tms helps governance. Governance is not only about security and audit logs—though those matter. Governance is also about ensuring that “the truth” in the enterprise logistics process is represented consistently across teams. If warehouse systems think a shipment is at dock, while carrier systems think it hasn’t been picked up, and customer order systems think delivery is already promised, teams lose confidence in the data and revert to manual workarounds. Uni Tms, when configured properly, becomes the system that reconciles these competing realities using predefined rules and verifiable milestones.
Enterprises exploring Uni Tms typically do so because logistics performance depends on timely, accurate information. Shipment events (e.g., pickup, in-transit scans, delivery confirmation), warehouse milestones (e.g., receiving, putaway, picking, packing), and order context (e.g., service level, promised delivery windows) must be consistent enough to drive downstream decisions.
Objectively, systems that fall under the broad theme of “transport and logistics management” are commonly designed around three responsibilities:
In that context, Uni Tms is generally treated as a technology enabler—its value emerges when it’s configured to reflect business rules, operational constraints, and the integrity of incoming data. A useful analogy is that visibility without execution is like having a dashboard without steering. Execution without measurement is like driving without a speedometer—you may move forward, but you cannot confirm you’re optimizing. Measurement without reliable event integrity is like using a thermometer with a broken sensor—you may think you know the temperature, but your actions will be based on false readings.
Therefore, Uni Tms’s practical role in enterprise logistics is not limited to tracking. It is also about structuring the process so that status changes reflect authorized actions and validated events. In mature deployments, teams implement a standardized event lifecycle: what events can occur, how they can be confirmed, what data fields are required, and how exceptions are handled. This lifecycle provides consistent behavior across carriers, facilities, and shipping methods.
Moreover, Uni Tms supports operational collaboration. When warehouse and transportation activities are managed by different teams, misalignment is inevitable unless there is a shared framework. Uni Tms can provide that framework by coordinating tasks and aligning how milestones relate to each other. For example, it can ensure that a shipment moves to “ready for pickup” only after packaging completion and label printing milestones occur. It can also determine that a delivery confirmation must be linked to the correct order line or shipment unit to update customer promises accurately.
An expert review usually starts with architecture questions. Uni Tms in many organizations becomes the “spoke” connecting multiple “hubs” of enterprise logistics:
The integration requirement is a central factor in overall cost of ownership—often more than the base platform license itself. Even a sophisticated Uni Tms module can underperform if item identifiers, location codes, carrier references, and unit-of-measure definitions are inconsistent. Integration is also where reality meets assumptions. Many projects fail not because the TMS is incapable, but because the systems do not speak a consistent data language. When a SKU code differs between warehouse and procurement systems, or when shipping point codes vary across regions, the workflow can break, and “visibility noise” becomes a permanent condition.
From an architecture standpoint, Uni Tms deployments typically need to decide how data flows: request/response versus event-driven messaging, batch versus near-real-time updates, and how reconciliation occurs when both internal and external systems report status. These decisions affect not only performance and cost, but also trust in the final status displayed to operational staff and customers.
In addition, enterprises must align integration with security and compliance expectations. Shipment and delivery data may involve customer-sensitive information, carrier contracts, and potentially regulated goods. Identity and access management—role-based authorization, audit logs, and environment separation—must be treated as first-class requirements. A TMS that connects to multiple systems may become a central data hub, so security posture should be designed early rather than bolted on later.
Finally, architecture should consider resiliency. Logistics operations cannot stop because a single integration endpoint is down. Mature Uni Tms implementations include retry logic, dead-letter queues (for event streams), idempotency handling (to avoid duplicate processing), and monitoring dashboards that alert teams before data gaps become operational problems.
Procurement and architecture teams frequently compare platforms using a structured approach. An expert evaluation typically focuses on the following areas:
Objective evaluation also requires you to define what “success” means in your organization—e.g., fewer manual status checks, improved on-time performance, or reduced exception-handling effort. However, these outcomes should be tied to baseline measurements and verified through controlled pilots rather than assumed during procurement. A useful practice is to define a “scorecard” with measurable criteria. Example categories include:
In enterprise logistics, the “best” product is not always the one with the most features—it’s the one with the most compatible process modeling and the strongest integration and data governance capabilities. A TMS can technically support many workflows but still create friction if it requires too much manual configuration or if data mapping is cumbersome. Evaluating usability and operational burden during pilots is as important as evaluating features.
Another critical selection criterion is how Uni Tms handles partial adoption. Many enterprises cannot replace every logistics capability at once. You may need transportation management first, followed by warehouse milestone orchestration later. A platform that supports incremental rollout—without breaking data integrity—is usually more valuable than one that forces a full “big bang” transformation.
When stakeholders ask about Uni Tms price, they often focus on the headline figure. In very enterprise deployments, the final budget depends on multiple components beyond the platform subscription or license. Typical cost drivers include:
Because you provided no specific numeric price or supplier name, this article refrains from stating unverified figures. Instead, it treats Uni Tms pricing as a scoped negotiation tied to modules, user counts, integration scope, environment needs (test/stage/prod), and service levels. For procurement, the top practice is to request a written scope-of-work that separates platform cost from services and operational responsibilities.
It’s also wise to think about cost in terms of total operating effort. Two vendors may offer the same license price, but one may require more manual reconciliation due to weaker event normalization or less flexible workflow configuration. Over a year, those differences can outweigh the license gap. Therefore, procurement teams should ask for pricing that includes key capabilities (or at least states clearly which capabilities are included versus “add-ons”).
Additional procurement realities include contract clauses for:
From a governance standpoint, you should ensure that acceptance criteria are explicit. The “cost” of poor acceptance is not just money spent—it's operational disruption. A disciplined procurement approach uses measurable acceptance criteria for integrations, event processing, and user workflows, not vague statements like “it should work.”
Your selection process for Uni Tms should also clarify supplier responsibilities. An expert approach emphasizes governance around deliverables, timelines, and quality criteria. Supplier/vendor roles often fall into categories such as:
If you are comparing suppliers, ask for evidence of delivery methodology: how requirements become configurations, how exceptions are validated, and how acceptance testing is performed. This is where many logistics system projects succeed or struggle. A vendor that cannot describe how it translates process requirements into system configuration may still be capable, but the enterprise bears higher implementation risk.
To reduce risk, it is useful to request:
Another practical element is escalation and operational support. After go-live, teams need clarity on who resolves what, how severity is defined, and how quickly a fix can be delivered or a workaround provided. Uni Tms sits in an operational loop; if an issue prevents milestone updates, customer service impact can be immediate. Therefore, contracts should cover the operational support expectations in realistic terms.
Vendor responsibilities also include documentation quality. In enterprise environments, the implementation team often changes over time—some developers leave, responsibilities shift, and operational staff become system owners. Clear documentation of workflows, event mapping rules, and integration endpoints prevents knowledge loss and reduces the “tribal knowledge” burden.
In logistics management, data quality is not a theoretical concern; it is operational. Uni Tms performance is tightly connected to whether your organization can supply stable identifiers and consistent event references. Common data quality conditions include:
Where these conditions are weak, teams usually experience “visibility noise”—dashboards that show too much unverified or mismatched data, leading to manual correction loops that negate the benefits of automation.
Data quality also affects analytics trust. If a shipment’s “departure” event is sometimes recorded as “in transit” and sometimes recorded as “pickup completed,” performance metrics like lane speed, dwell time, and on-time delivery rates become inconsistent. That inconsistency makes it difficult to identify real operational bottlenecks, and continuous improvement efforts lose direction.
To prevent these problems, enterprises commonly establish a data governance program during implementation. This includes:
Another important aspect is event field completeness. Many integration feeds provide partial data. Uni Tms can still process events, but the quality of decision-making depends on whether essential fields exist. For example, if carrier event feeds do not include a consistent tracking reference, the system may not reconcile events to the correct shipment. Similarly, if proof-of-delivery artifacts lack a signature or delivery timestamp field, customer promise updates can become unreliable.
Enterprises benefit when Uni Tms is configured to distinguish between “reported” events and “verified” milestones. Verified milestones may require validation steps such as confirmation from specific carrier event types, scan source criteria, or warehouse confirmation milestones. This reduces the risk of customers receiving premature or incorrect updates.
It is common to hear that logistics optimization tools “improve delivery performance,” yet the improvement depends on operational discipline. Industry research consistently emphasizes that performance outcomes are influenced by process design, planning accuracy, and coordination across stakeholders—not only by software availability.
To ground expectations objectively, refer to widely published logistics and supply-chain analyses such as:
Because this article cannot access your specific documents, it does not claim quantitative results for Uni Tms deployments. Instead, it provides a method for validating expected benefits through baseline measurement and controlled rollouts.
In practice, performance improvements typically emerge when the system creates consistent process behavior across teams. Examples of measurable outcomes enterprises often seek include:
However, these outcomes are not automatic. If Uni Tms is implemented without aligning operational authority—who is allowed to approve reroutes, who confirms pickup completion, who confirms delivery exceptions—then the system might show status but cannot enforce correct transitions. In that scenario, the TMS becomes a record-keeping tool rather than an operational system.
To align software behavior with logistics reality, enterprises must define a “process authority matrix.” This matrix clarifies which roles can make which changes, and how changes affect event verification and customer promise updates. When such authority is clear, the organization can improve performance because it trusts the system and uses it consistently.
The following supplements the main narrative with a practical framework. It is intended as a comparison and readiness guide for teams assessing Uni Tms and planning deployment scope.
| Phase | What to Compare | Conditions/Requirements | Typical Output |
|---|---|---|---|
| 1. Scope Definition | Which logistics workflows Uni Tms must cover (warehouse receiving, dispatch, proof-of-delivery, etc.) | Documented process map; named operational owners; defined “minimum success metrics.” | Requirements backlog and workflow ownership model. |
| 2. Data Readiness Review | Master data consistency between systems (locations, SKU/item IDs, carrier references) | Code lists agreed; reconciliation rules for identifiers; data governance roles assigned. | Data quality plan and migration checklist. |
| 3. Integration Design | Integration patterns (APIs, middleware, event-driven messaging) and responsibilities | Endpoint specifications; security approach; test environments prepared. | Integration architecture and test cases. |
| 4. Configuration and Workflow Build | Rule coverage: exception handling, status transitions, audit logging | Defined exception categories; approval steps; role permissions matrix. | Configured Uni Tms workflows and user roles. |
| 5. Testing and Acceptance | Scenario validation across edge cases (late scans, partial deliveries, reroutes) | Acceptance criteria aligned to operational outcomes; sign-off responsibilities defined. | UAT results, defect triage, acceptance sign-off. |
| 6. Cutover and Training | Change management: who does what on cutover day | Runbook, rollback strategy, training completed per role. | Go-live readiness report. |
| 7. Post-Go-Live Optimization | Performance validation and continuous improvement loop | Monitoring dashboards; weekly review cadence; backlog management. | Optimization backlog and release plan. |
To make this framework more actionable, it helps to expand each phase into key “decision questions” enterprises should ask. These questions reduce ambiguity and prevent teams from treating the implementation as purely technical work.
Phase 1: Scope Definition — decision questions
Phase 2: Data Readiness Review — decision questions
Phase 3: Integration Design — decision questions
Phase 4: Configuration and Workflow Build — decision questions
Phase 5: Testing and Acceptance — decision questions
Phase 6: Cutover and Training — decision questions
Phase 7: Post-Go-Live Optimization — decision questions
By asking these questions, enterprises treat the implementation as an operational transformation rather than a system installation.
Even when implementation is technically sound, operations teams may find that Uni Tms benefits depend on governance conditions. Consider these requirements:
In practice, “exception ownership” is the factor that most strongly determines whether teams trust the system. If a shipment status changes to an exception state but no clear team is responsible for action, the process stalls. If multiple teams try to resolve the same exception without coordination, effort duplicates and confusion grows.
Successful operations also rely on consistent carrier data exchange. Carriers may use different naming conventions for events like “picked up,” “departed,” “arrived at facility,” and “out for delivery.” Uni Tms needs mapping and normalization rules that translate carrier-specific codes into canonical event types your operations can understand and rely on. Without normalization, visibility dashboards can become inconsistent and undermine the TMS’s value.
Cutover stability matters because logistics operations do not pause just because software is changing. Enterprises should plan cutover around operational cycles: avoid peak seasons, align staffing and support availability, and coordinate with warehouse and dispatch leadership. During cutover, the biggest risk is often not technical failure alone, but operational misunderstanding. For example, if labels are printed according to new rules but warehouse workers are not trained on what those labels mean in the new workflow, you might see scanning errors that cascade into incorrect status transitions.
Training quality should include scenario-based exercises. Users need to know how to interpret event timelines, how to handle partial shipments, and how to escalate exceptions. A system that is easy to navigate can still fail operationally if users do not understand the rules that drive transitions and notifications.
Finally, auditability is essential for enterprise logistics governance. Audit logs allow you to answer questions like: who changed a delivery promise date, why did a shipment move to a “rerouted” state, and what evidence was used? Without auditability, it becomes difficult to investigate operational issues and enforce accountability.
From a field-oriented standpoint, the biggest value of Uni Tms often appears when the organization stops relying on “happy path” assumptions. Real logistics contains deviations: delayed scans, carrier substitution, partial warehouse picks, and last-minute rescheduling.
An expert design approach therefore encourages teams to:
This orientation reduces operational risk and supports more consistent customer experience—an outcome that is measurable through verified performance reporting after go-live.
To implement exception-oriented design, enterprises should start by listing the most frequent operational deviations. Then, for each deviation, define:
Many enterprises overlook the downstream effects. For example, if an exception resolution action changes the shipment’s expected delivery date, it should also update or invalidate any customer-facing communications that were based on earlier predictions. Otherwise, customers may receive conflicting information and lose trust.
Additionally, the system should distinguish between “data quality exceptions” and “operational exceptions.” Data quality exceptions occur when IDs do not match, codes are invalid, or records are incomplete. Operational exceptions occur when logistics execution deviates from plan (missed pickup window, failed delivery attempt, carrier delay). Conflating them leads to misdirected effort: teams fix the wrong problem.
A robust exception design also supports a learning loop. When the system records how exceptions are resolved and by whom, organizations can identify recurring issues. For instance, if the same carrier lane produces repeated “missing pickup” exceptions, it may indicate that pickup manifests are being generated incorrectly or carrier handoff practices need adjustment. That knowledge can then inform process improvements outside the TMS as well.
Uni Tms is typically used to manage logistics workflows and shipment visibility across transportation and warehouse activities, helping teams coordinate execution and report performance based on event and order context.
Very organizations determine price through a scoped package: required modules, number of users, integration complexity, data migration needs, environment setup, and support/implementation services. A written scope-of-work helps separate platform costs from implementation and operational expenses.
Data quality determines whether event visibility is reliable. Standardized location codes, consistent item identifiers, aligned unit-of-measure, and mapped carrier references are common prerequisites for stable operations.
In very enterprise environments, integration is expected. The key is to confirm integration methods (e.g., APIs and middleware), data mapping rules, security requirements, and how reconciliation and testing will be handled.
Common risks include unclear workflow ownership, inconsistent master data, incomplete integration testing for edge cases, and insufficient training. These risks can be mitigated by detailed acceptance criteria, realistic scenario testing, and role-based onboarding.
Use baseline measurements before go-live, define KPIs aligned to operational outcomes, and evaluate performance after cutover through controlled review cycles. Document what improved (e.g., exception handling time or audit coverage) and verify results with reliable operational data.
Request implementation methodology details, integration documentation expectations, responsibilities for data migration and acceptance testing, and post-go-live support terms (including escalation paths and release practices).
Uni Tms is top understood as an operational system that transforms logistics information into governed workflows. The very reliable path to value is disciplined preparation: precise scope definition, data readiness, integration planning, and exception-oriented process design. When these elements are addressed, enterprises can move from fragmented visibility to consistent execution—supported by reporting that stakeholders can trust.
If you want, share your intended logistics coverage (e.g., warehouse receiving to delivery proof, or transportation dispatch only), your current systems, and your target regions; I can help you translate the above framework into a deployment checklist and evaluation questions tailored to your operational context—keeping expectations objective and grounded in verifiable requirements.
Uni Tms: Industry Insights and Procurement Guide
Uni Tms: Supplier Insights and Practical Buying Guide
Uni Tms Overview for Procurement and Compliance
Uni Tms: A Practical Guide for Operations Optimization
Understanding Uni Tms for Modern Operations
Uni Tms: Technical Overview and Supplier Considerations
Uni Tms: Enterprise Logistics Management Insights
Uni Tms Guide for Reliable Operations and Planning
Uni Tms: Internet Provider Options Compared
Uni Tms: Enterprise Logistics Management Insights
This guide examines Uni Tms as a core platform for enterprise logistics visibility, workflow control, and performance management. In the background, it reviews how transportation and warehouse systems align, what data quality demands exist, and why integration matters. The article then offers objective selection criteria, operating conditions, and practical FAQs for stakeholders evaluating deployments.
Using an Ageism Questionnaire to Improve Workplace Inclusion
This guide explains how to use an Ageism Questionnaire to assess age-based bias, plan targeted improvements, and track progress with objective methods. Background sections define ageism and why structured assessment matters. It then provides practical steps, validation considerations, and common implementation conditions.